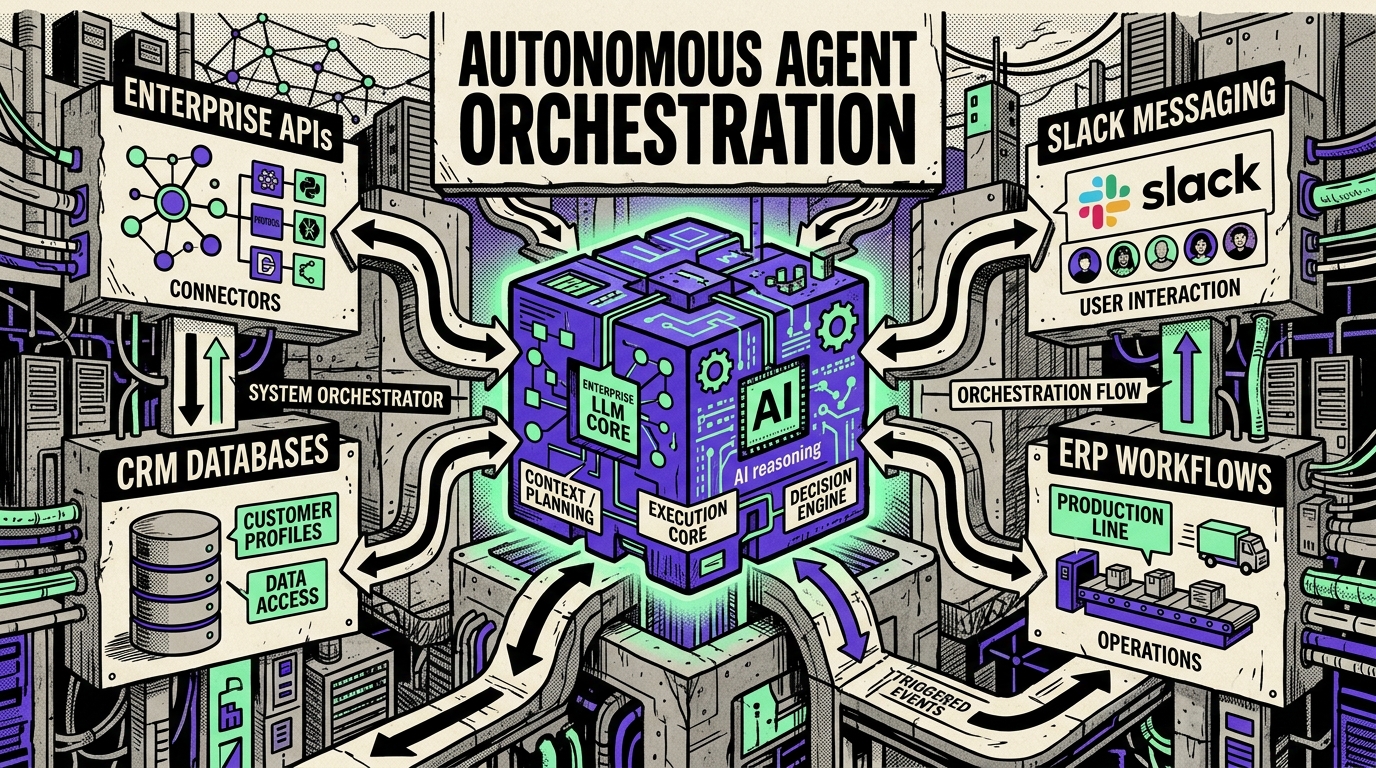
An AI agent is useful only when its allowed actions can be constrained and evaluated. I use explicit state and limited tools for agentic systems; the BMRC project discussed below is a separate documented n8n, OpenAI, Supabase and Gmail workflow, not evidence that it used LangGraph or RAG.
State machines beat free-form loops
The biggest mistake in agent design is an open-ended 'think until done' loop. In production I model agents as explicit graphs with LangGraph: each node has a clear responsibility, and transitions are constrained. This makes the agent auditable — critical for healthcare and enterprise compliance.
Grounding agents with RAG
Retrieval is relevant when an application needs approved, changing source material, but it is not required for every agent. The retrieval layer and the action workflow should be evaluated separately.
For the BMRC Hospital AI Feedback Agent, the documented stack is n8n, OpenAI, Supabase and Gmail API. The public case study describes multilingual feedback classification and routing; it does not claim a vector database or LangGraph implementation.
The rule I follow
Give the agent the smallest possible action space, the richest possible context, and full observability. Autonomy without auditability is a liability, not a feature.